
Another researcher claims OpenAI trained models on user conversations
A new claim suggests OpenAI trained its AI models on user conversations before marketing the results as a major breakthrough.
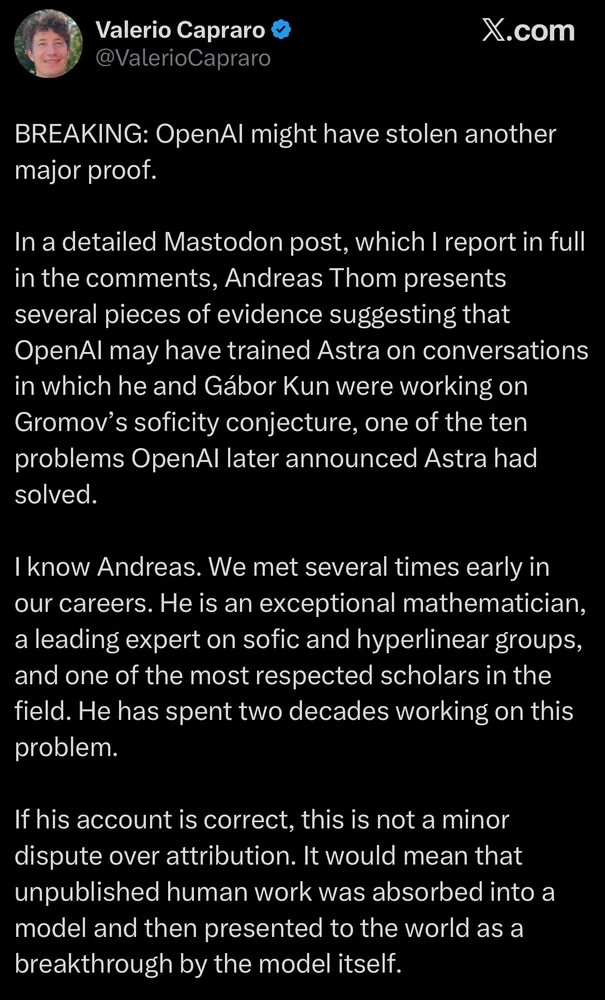
A fresh controversy is brewing in the tech world regarding the training data behind advanced artificial intelligence models. Another researcher has come forward with claims that OpenAI utilized user conversations to train its systems before presenting the outcomes as groundbreaking technological advancements.
As discussed widely on platforms like Hacker News, these allegations put the spotlight back on the transparency and data collection ethics of major AI labs. Critics point out a potential disconnect between how foundational models are actually built and how their capabilities are marketed to the public.
For the tech and AI community in Uzbekistan and the wider region, such news highlights the growing importance of data governance. As local developers increasingly adopt global AI solutions, understanding the ethical origins of these models remains crucial.
The ongoing discussions signal a broader demand for accountability within the tech industry. Users and regulators alike are expected to scrutinize how large language models gather training data, potentially leading to stricter compliance standards.
OpenAI has yet to issue a comprehensive response to these specific claims, but the debate adds to the mounting pressure on AI companies to be fully transparent about their data sourcing and research methodologies.


