
OpenAI's Jalapeño Chip Sets New Inference Speed and Efficiency Benchmarks
According to Semianalysis InferenceX test, the Jalapeño processor delivers higher token output per user and greater throughput per kilowatt than today's leading AI chips.
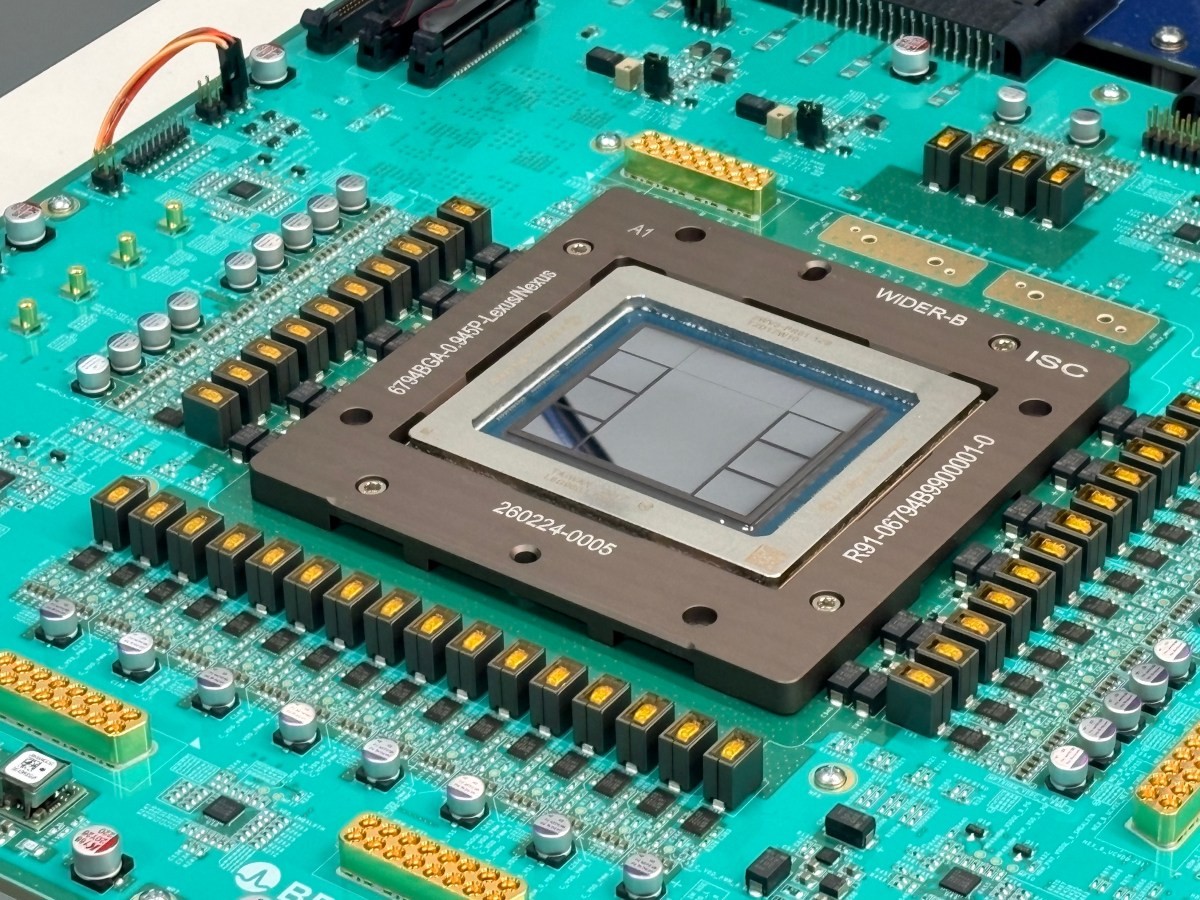
OpenAI unveiled its Jalapeño chip as a purpose‑built accelerator designed to handle large‑scale inference workloads with minimal latency.
To evaluate its performance, the chip was run through Semianalysis’s InferenceX benchmark, which measures how many tokens a system can generate per user and how much computational throughput it achieves per kilowatt of power.
The results showed that Jalapeño outperforms the current state‑of‑the‑art AI processors in both metrics, delivering more tokens per user and higher throughput per kilowatt.
These gains translate into lower operating costs for data centers and make it feasible to run more demanding AI services without a proportional increase in energy consumption.
For regions such as Uzbekistan and the wider Middle East, where access to affordable, high‑performance AI infrastructure is still growing, chips like Jalapeño could help accelerate adoption of advanced AI applications.


