Embedded AI evaluators won’t be an easy solution, Hugging Face’s policy chief says
Hugging Face policy chief Irene Solaiman highlights the complexities and maturing nature of AI model benchmarking.
AI labs have staked their reputations on model benchmarking, relying on supposedly neutral and accurate systems of evaluation designed to measure whether one AI product is superior to another.
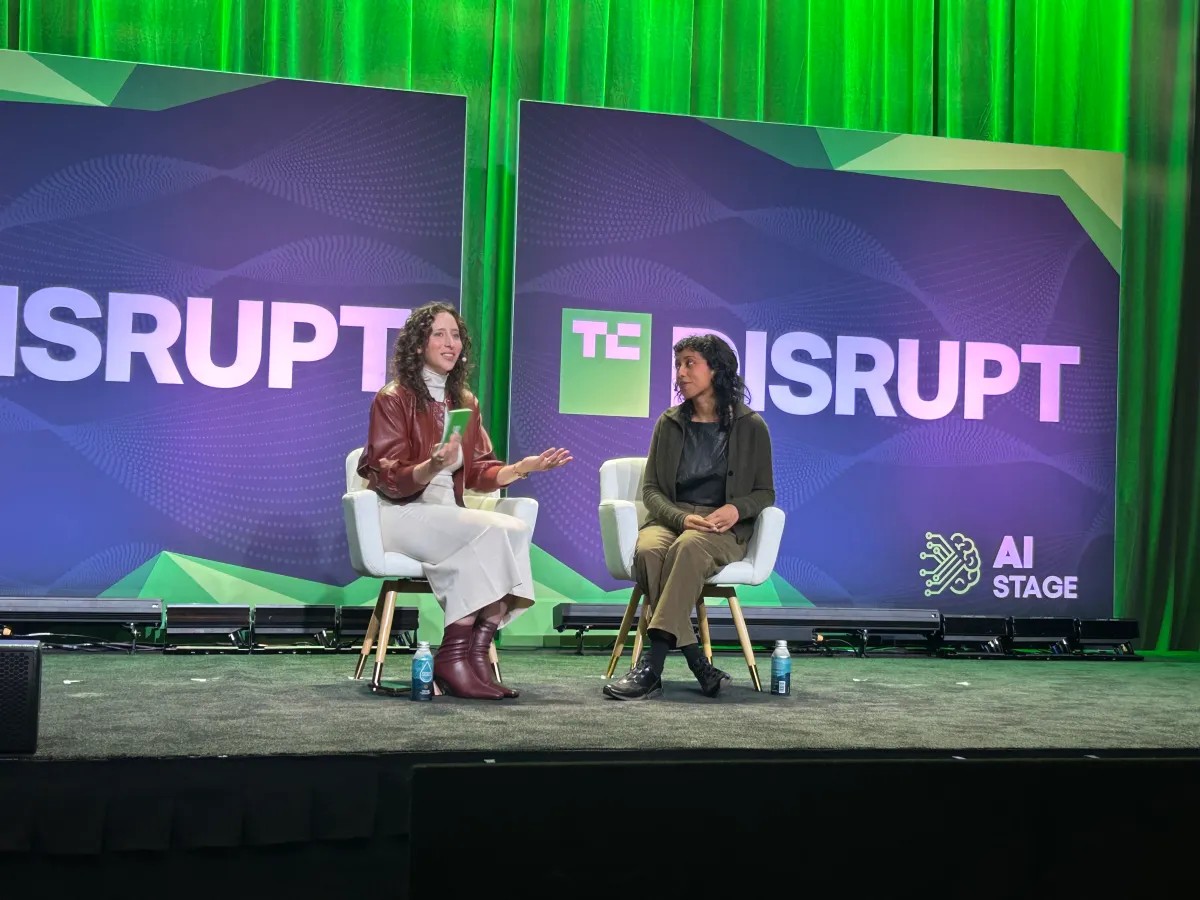
However, during a discussion at TechCrunch, Irene Solaiman, Hugging Face’s chief policy officer, pointed out that the methods behind these evaluations are complicated and still maturing.
As the artificial intelligence landscape continues to evolve rapidly, establishing reliable and objective benchmarks remains a critical yet challenging task for developers and researchers alike.
The admission that evaluation systems are not straightforward highlights the ongoing growing pains within the tech industry as it strives for transparency and standardized testing.
For tech ecosystems and developers globally, staying aware of the limitations in AI benchmarking helps in making more informed decisions when adopting and deploying modern machine learning models.