
Benchmarking Qwen Quantizations: 4-bit Holds Up, 1-bit Collapses
Recent benchmark tests on language model quantizations reveal that 4-bit compression retains strong performance, while extreme 1-bit quantization leads to complete model failure.
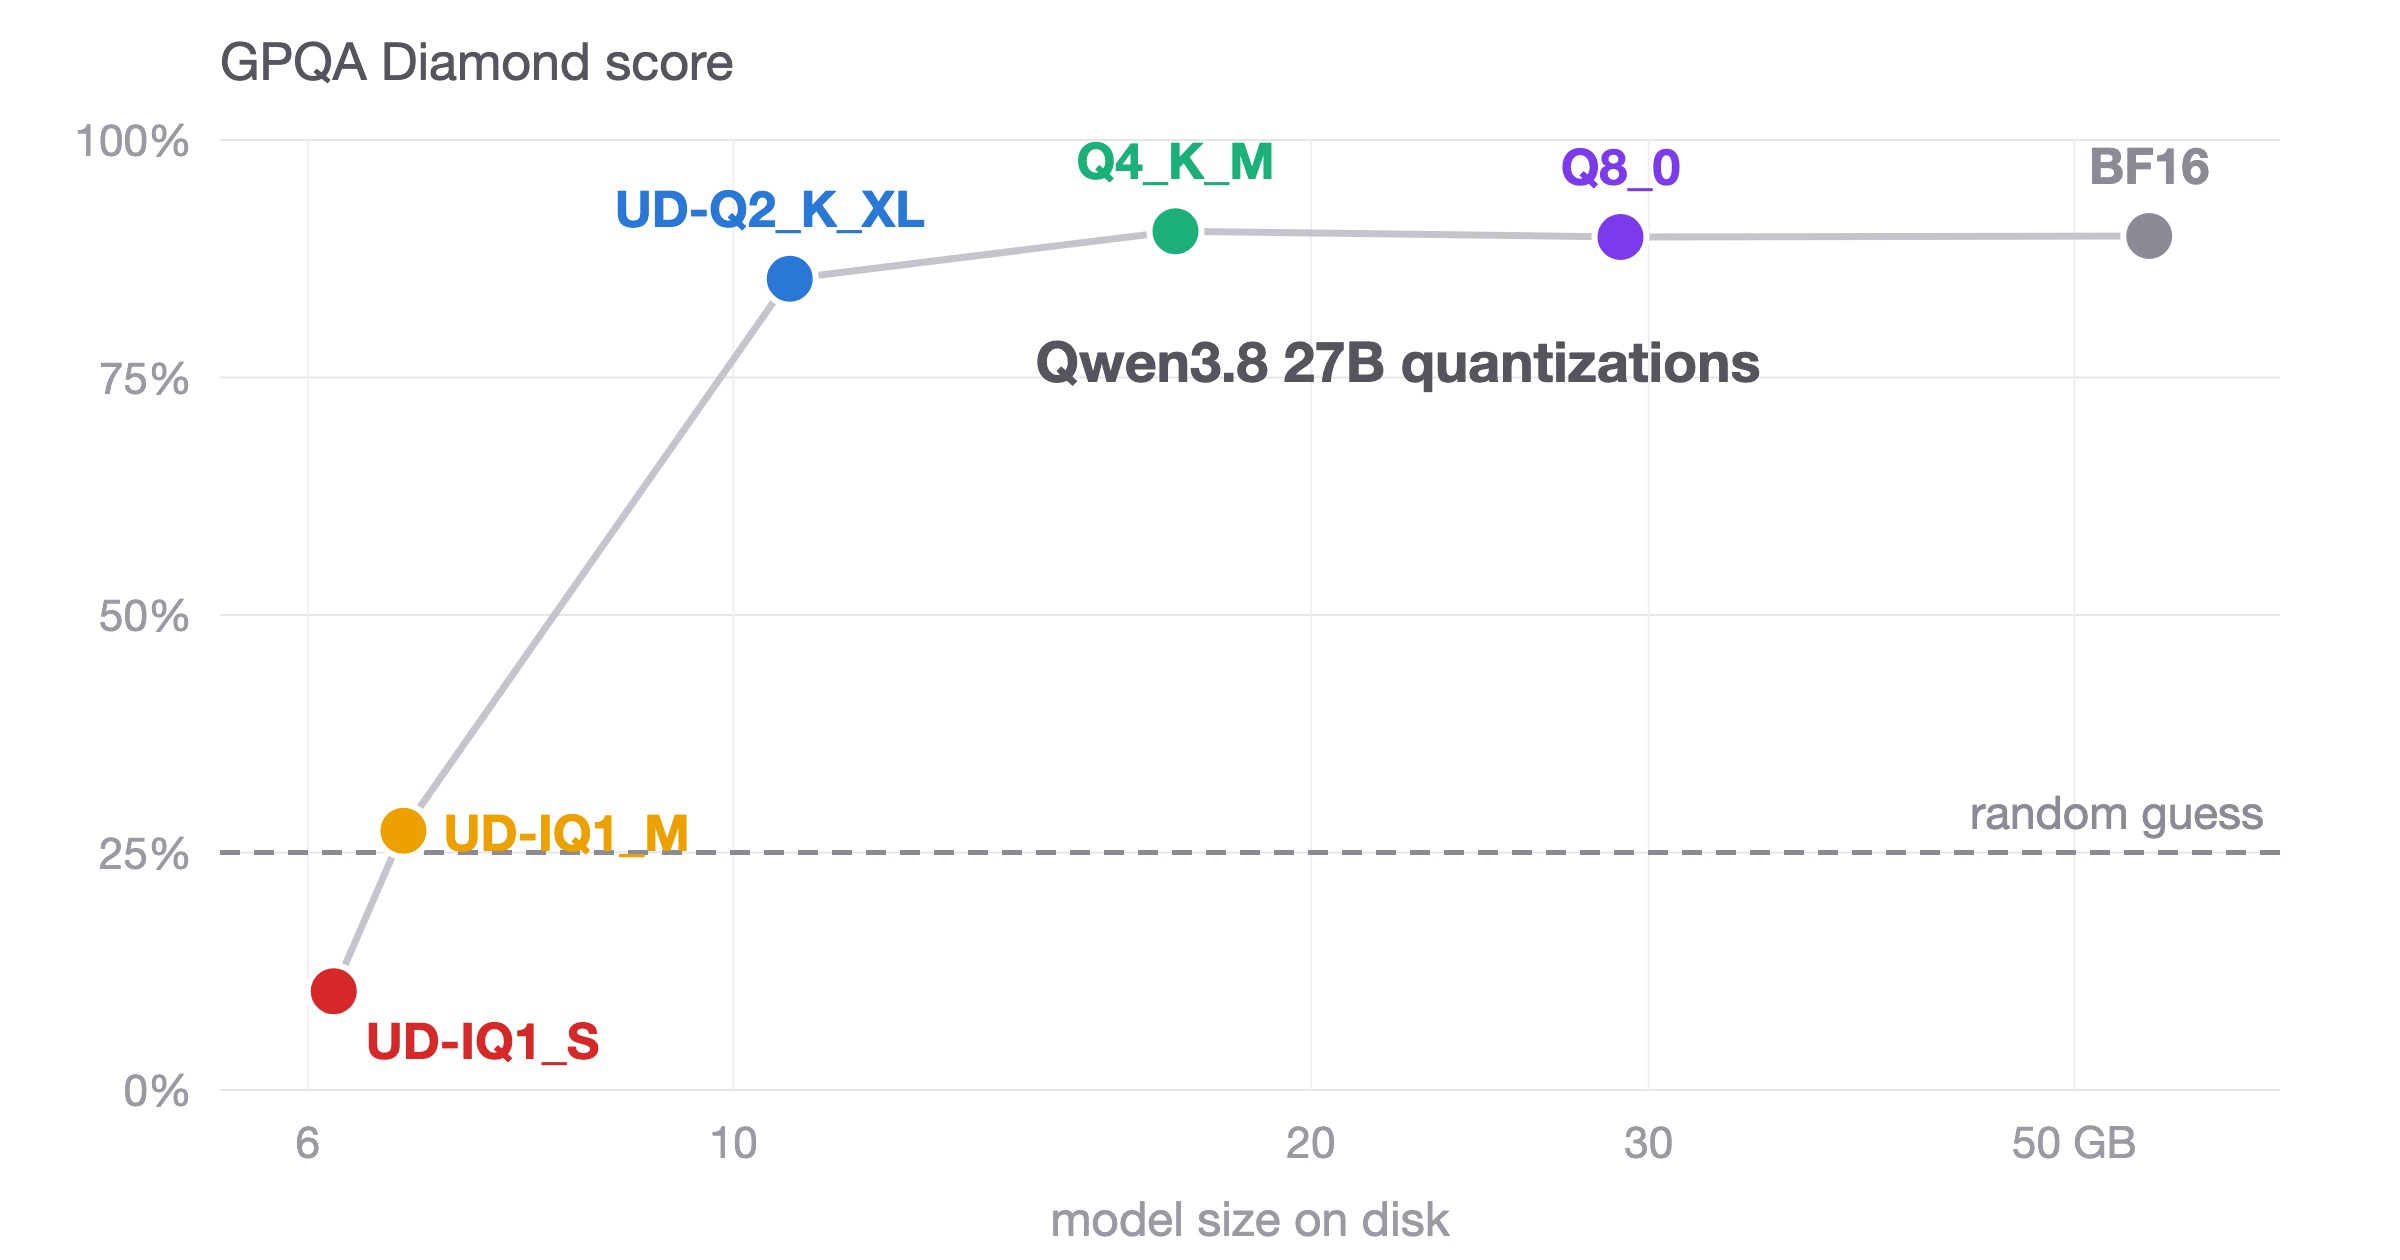
The AI developer community has been discussing new benchmark results focusing on the quantization of open-source language models. These tests evaluate how different bit-level compression techniques affect the overall performance and accuracy of models based on the Qwen architecture.
According to the benchmark data shared and discussed on Hacker News, 4-bit quantization proves to be a reliable sweet spot. Models compressed to 4 bits retain a vast majority of their original capabilities and reasoning skills while significantly reducing memory footprint and hardware requirements.
Conversely, pushing compression to extreme limits, specifically down to 1-bit quantization, results in a complete system collapse. At this level of compression, the model loses its core logic, coherence, and text generation abilities, rendering the output entirely unusable.
These practical findings are extremely valuable for developers and infrastructure engineers looking to run large language models locally or on resource-constrained hardware. They clearly define the boundaries of how far model weights can be compressed without sacrificing functionality.


