Box integrates Nvidia Nemotron into new content retrieval system
Box is launching Box Content Retrieval using Nvidia's Nemotron to boost query speed by 4x and improve accuracy for enterprise AI agents.
At its recent developer conference, Box unveiled Box Content Retrieval, a new feature that integrates Nvidia’s Nemotron embedding system directly into its platform. This update allows AI agents to process queries with unprecedented speed and efficiency.
- Queries are answered four times faster. - Error rates are reduced by 20%. - Token usage is cut by 90%, significantly lowering operational costs. - The system leverages Nvidia’s open-weight Nemotron Embed models.
Enhancing Agent Performance
Box Content Retrieval uses Nemotron-processed metadata to move beyond simple keyword searches. By mapping underlying concepts, the system allows agents to retrieve relevant document chunks instead of parsing entire files. This provides more context-aware and accurate responses for users.
The implementation is based on the Nemotron Embed project, which topped the MTEB benchmark in July. Nvidia’s VP of generative AI, Kari Briski, highlighted that this technology is crucial for developers building automated retrieval systems that require deep semantic understanding of data.
Read alsoRevolut moves 2000 engineers to self-hosted GLM: 90% cost cutScalability and Deployment
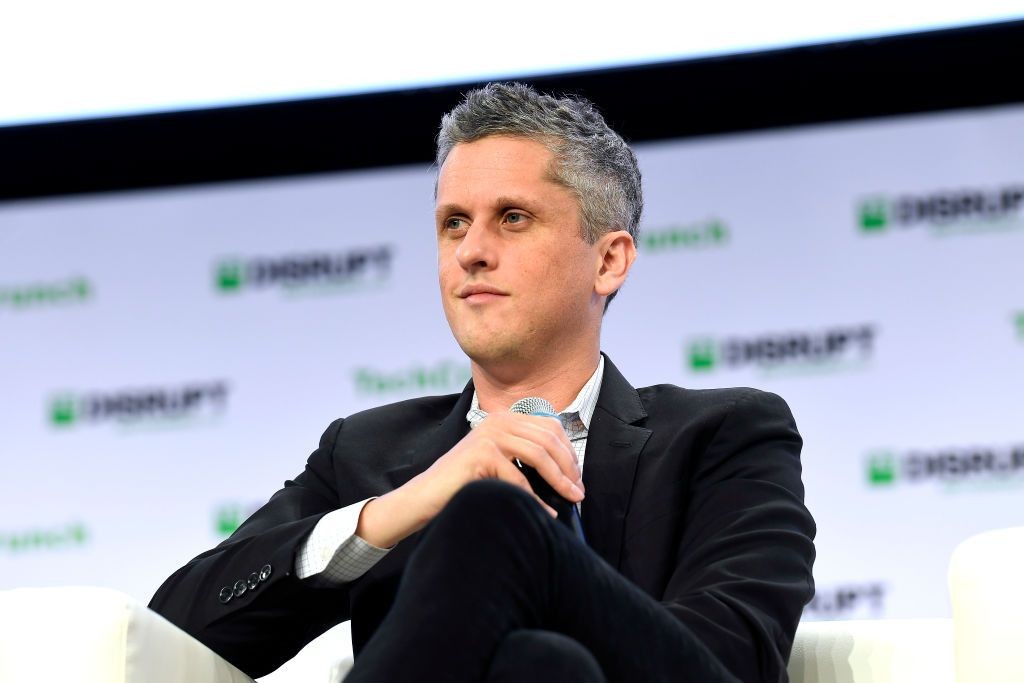
The system is expected to roll out to all Box Enterprise Advance customers by early next year. Box CEO Aaron Levie noted that the feature bundles five distinct technologies into one simple API, making it a robust, proprietary-grade tool that combines Nvidia's power with Box's existing permission and metadata security structures.
Strategic Implications
For organizations leveraging enterprise data, this represents a major step toward practical AI integration. By reducing token consumption by 90%, businesses can scale their internal AI tools much more affordably. This level of optimization is essential for companies looking to maintain high-performance AI agents without incurring massive computational overhead.
Source: TechCrunch