Underdog showcases a new 32MB speech and music generation model
Startup Underdog has released Woof, a 31.7MB speech and music model that runs locally inside the browser without requiring internet.
·2 min read
While major artificial intelligence companies race to build massive models that demand heavy processing power, some researchers are focusing on efficient edge devices. Startup Underdog has introduced a remarkably compact voice model named Woof.
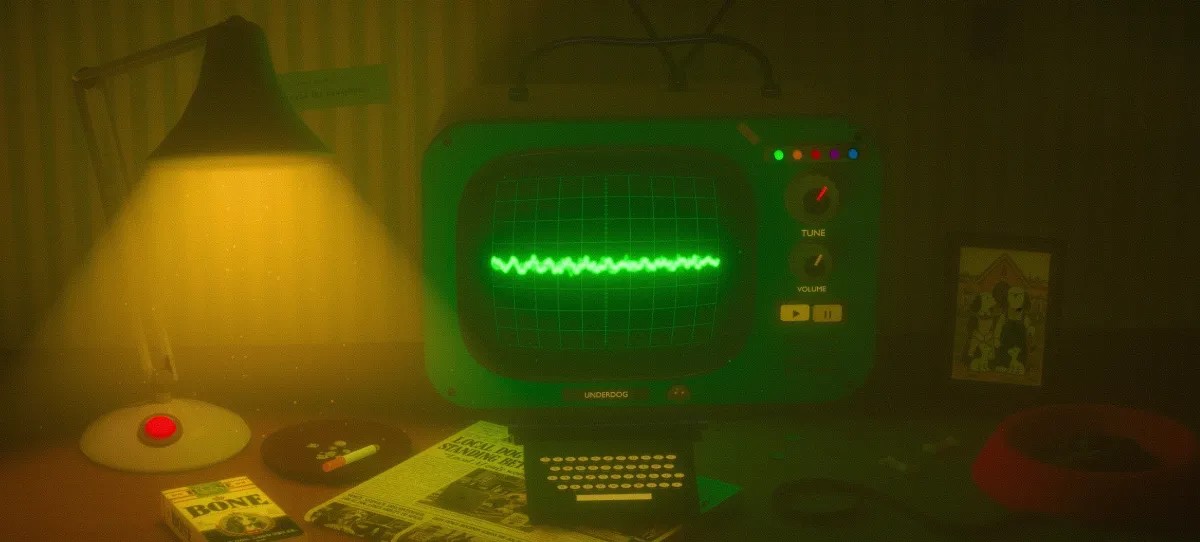
- Underdog released a retro browser game built on its new Woof voice model.
- The model is only 31.7 MB in size and runs directly in the browser offline.
- It features 31 million parameters and is fully open for public download.
- The company previously launched Bark, a 167MB speech-to-text model.
Inside the Woof Model Demo To showcase the capabilities of the new text-to-speech model, Underdog developed a browser game featuring a retro tech aesthetic. Users can type anything using their keyboard, and the game instantly speaks the text back. Additionally, players can rotate an interactive tuner to generate different types of music. The entire process runs locally through Underdog's speech generation architecture without needing an internet connection. The development team emphasizes data ownership and privacy as a counterweight to traditional cloud-based AI providers.
Technical Specs and Founder Vision The Woof model contains 31 million parameters and has a footprint of just 31.7 MB, allowing it to execute smoothly on standard consumer hardware. Underdog founder Sigil Wen noted that the initiative stems from a desire to let users own their data and run capable AI models locally on the hardware they already own. Alongside Woof and the earlier Bark transcription model, Underdog has also developed a 27-billion-parameter model designed to operate locally on laptops, reflecting a broader strategy toward decentralized and private artificial intelligence applications.
Industry Impact and Future Outlook The emergence of sub-40MB generative models indicates a shift toward efficient local processing, reducing reliance on expensive cloud infrastructure. For developers and businesses, this creates new opportunities for responsive voice assistants, dictation tools, and personalized audio applications that prioritize user privacy and operate seamlessly offline.
Source: TechCrunch